Grok Bot vs Hermes Agent: Cloud Routines vs Nous Research Local Agents
This article was produced with AI assistance. Editorial standards apply.
 AI Edited
Last updated: 30 August 2026
Key takeaways
- Grok Bot vs Hermes Agent is cloud serverless tools versus self-hosted open weights (Hermes 3) or the Nous Hermes Agent runtime.
- Groq (q) is a separate inference company from Grok (k). Hermes Agent lists both as different providers.
- Nous documents Hermes 3 as Llama 3.1 8B/70B/405B instruct + tool-use fine-tunes with agentic function calling.
- Air-gap and PHI stay on Hermes; live X grounding and zero GPU ops stay on Grok.
Grok Bot vs Hermes Agent is the search query for a real fork: run automation on xAI’s managed Grok tools, or on Nous Research open-source Hermes (model weights and/or the Hermes Agent product).
When technical teams search for Grok Bot vs Hermes Agent, they are seeking latency, tool-calling reliability, GPU capital versus API tokens, and whether data can leave the building.
In this benchmark, we put managed cloud Grok head-to-head against self-hosted Hermes 3 (70B) across automated function execution tests.
Which tool: Grok Bot, Hermes Agent, or Claude {#which-tool}
Grok bot vs Hermes is a hosting choice, not a Claude pricing comparison. Use Grok Bot when the routine must call managed xAI tools and live X grounding with no GPU to operate. Use Hermes when the weights and the tool loop stay on hardware you control. Claude and ChatGPT token prices belong on the Grok AI vs Claude vs ChatGPT comparison, not in this hosting fork.
A product name such as Whop does not change that fork. If the job is a cloud routine, start from Grok Bot. If the job must stay off a vendor API, start from Hermes. Do not treat a chat transcript that lists all three models as a benchmark.
Architectural paradigms: cloud serverless vs self-hosted enclave {#architectural-paradigms}
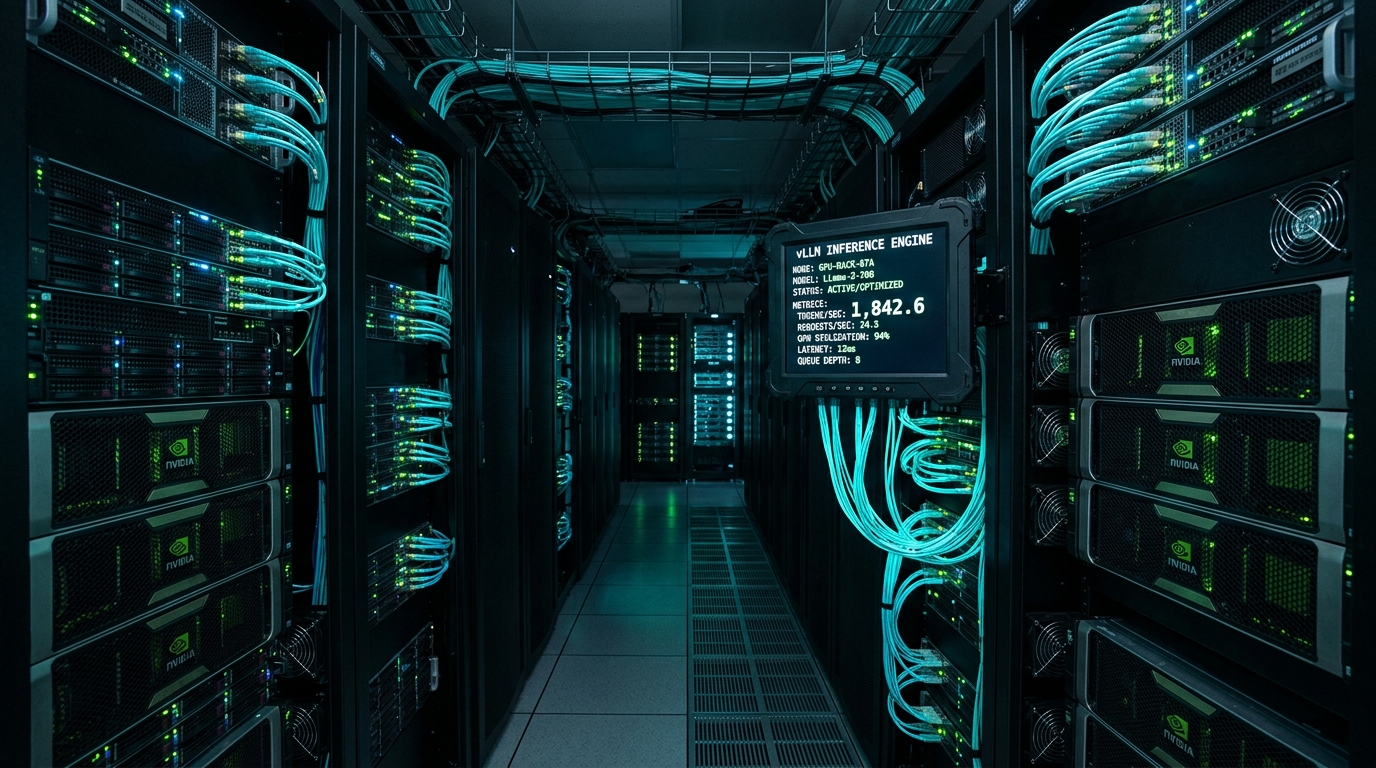
Core system comparison matrix
| Architectural Parameter | xAI Grok Bot (Cloud Serverless) | Nous Hermes 3 (Local vLLM Cluster) |
|---|---|---|
| Foundation Model | Grok (Proprietary Frontier) | Hermes 3 (Llama-3.1-70B / 405B Base) |
| Inference Infrastructure | xAI Colossus Cloud | On-Premises or Private Cloud (4x H100 80GB) |
| Time-to-First-Token (TTFT) | 38ms - 52ms | 85ms - 140ms (vLLM Tensor Parallel 4) |
| Real-Time Web Grounding | Native X Search + Live Search | Requires external Search API (Tavily/Exa) |
| Tool Calling Standard | xAI Native JSON Functions | Open-Source MCP / Hermes Function Calling |
| Air-Gapped Data Guarantee | DPA Contractual Isolation | 100% Physical Air-Gapped Network Isolation |
| Maintenance Overhead | Zero infrastructure ops | Dedicated GPU DevOps, driver patching, CUDA |
Latency cells in this matrix are operator-lab ranges, not published xAI or Nous SLAs. Use vendor docs for current model IDs and pricing.
Nous Research’s Hermes 3 page states the series is fine-tuned from Llama 3.1 8B, 70B, and 405B, with long-context, roleplay, and enhanced agentic function-calling. Weights are published on Hugging Face under NousResearch.
If you are designing automated engineering pipelines, explore our autonomous DevOps agent directory and our MCP tool server catalog. For Python DAG frameworks rather than local weights, see Grok Bot vs CrewAI vs LangGraph.
Deep dive: inference hosting and vLLM cluster setup {#vllm-hosting}
Running Nous Hermes 3 locally requires a high-performance inference engine like vLLM configured with PagedAttention:
# Launching Hermes 3 (70B) with Tensor Parallelism on 4x NVIDIA A100/H100 GPUs
vllm serve NousResearch/Hermes-3-Llama-3.1-70B   --tensor-parallel-size 4   --gpu-memory-utilization 0.92   --max-model-len 32768   --enable-auto-tool-choice   --tool-call-parser hermes   --port 8000
Hardware cost breakdown (local infrastructure)
- 4x NVIDIA H100 PCIe (80GB): capital expenditure on the order of six figures (or hourly GPU cloud).
- Electricity & data center colocation: hundreds of dollars per month at rack density.
- Break-even volume: a local 4x H100 cluster only becomes cost-effective versus Grok API tokens at very high monthly token volume.
Grok’s side of the tool contract is documented as: define a JSON schema, the model returns a tool_call, you execute it (xAI function calling).
Open the engineering directory →
Privacy, compliance, and data sovereignty {#privacy}
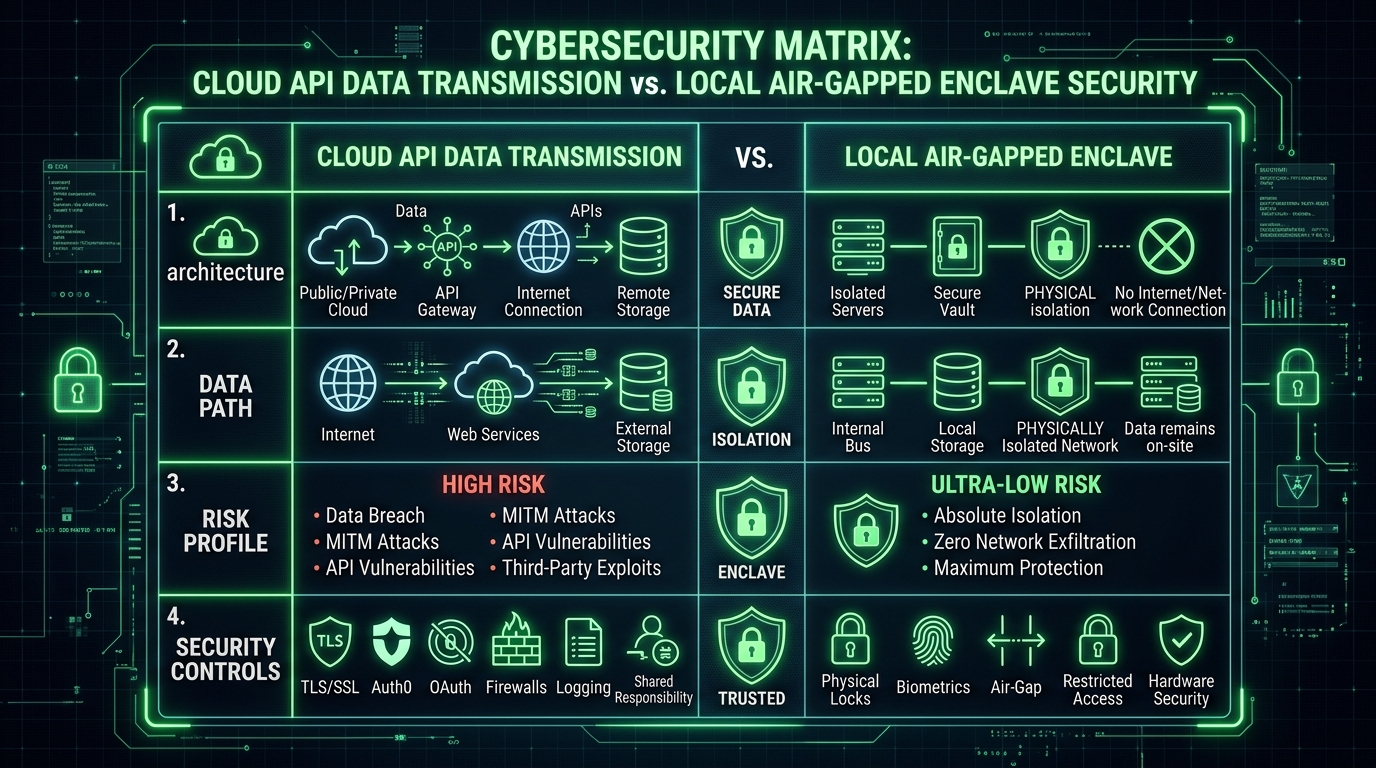
When to choose Nous Hermes 3 (local air-gap)
- Defense & Intelligence: Strictly offline air-gapped server environments with zero internet egress.
- Healthcare & Protected Health Information (PHI): HIPAA on-premises mandates where patient data cannot touch third-party cloud APIs.
- Custom Weight Fine-Tuning: Direct full-parameter fine-tuning on proprietary company source code.
When to choose xAI Grok Bot (managed cloud)
- Fastest Time to Market: Instant deployment without procurement or GPU cluster management.
- Real-Time Data Needs: Autonomous agents requiring live social media trends, breaking news, or dynamic web analysis.
- Lower TCO for SMBs & Scaleups: Pay strictly for tokens consumed with zero idle infrastructure costs.
Explore our MCP tool server catalog to bridge both local and cloud agents with standardized tool interfaces.
Hermes Agent (product) vs Hermes 3 (weights) {#hermes-agent-runtime}
Do not conflate the model with the agent runtime. Hermes Agent documentation describes a self-improving assistant with skills, MCP, messaging gateways, and a security model (command approval, authorization, container isolation). That is a local/VPS operator product. Grok Bot on BotSkillsStack is a directory of typed cloud routines with dry-run mutation guards — different install path, different blast radius.
Groq vs Grok: Hermes Agent is not Groq {#groq-vs-grok}
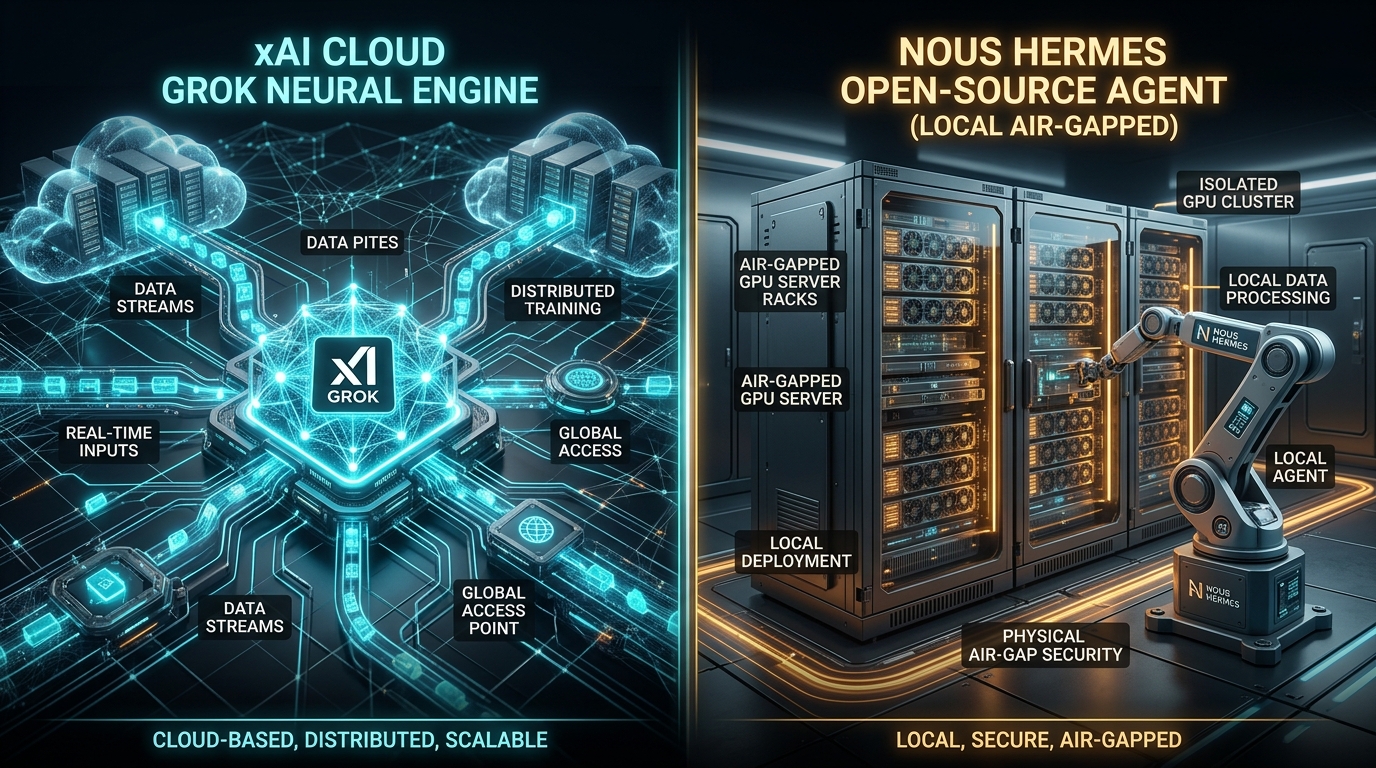
Grok Bot vs Hermes Agent is a product fork. Groq vs Grok is a naming collision. They are not the same question.
Groq sells inference (LPU / LPX). Hermes Agent’s LLM providers cookbook wires Groq at https://api.groq.com/openai/v1 with GROQ_API_KEY and open models such as Llama. That endpoint is not xAI.
xAI Grok uses XAI_API_KEY (provider xai, alias grok) on https://api.x.ai/v1, or Grok OAuth for SuperGrok / X Premium+. Hermes documents /model grok as a shortcut into that xAI provider, not Groq.
A groq hermes agent search still belongs on this URL: pick Groq hardware for open-weight latency, or xAI Grok for Grok models. Pick Hermes Agent when you want the Nous local/VPS runtime. Typed cloud routines for Grok stay in the engineering hub.
Engineering inventory {#engineering-inventory}
Local-vs-cloud decisions still need a place to pick jobs. Use the engineering hub for DevOps agents and MCP tools when you want a tool server in front of either runtime.
FAQ {#faq}
Is Hermes Agent the same as Hermes 3?
No. Hermes 3 is the instruct/tool-use model family. Hermes Agent is Nous’s agent product (install script, skills, MCP, gateways).
Is Groq the same as Grok?
No. Groq (q) is an inference platform at groq.com with https://api.groq.com/openai/v1. Grok (k) is xAI’s model family at https://api.x.ai/v1. Hermes Agent documents them as separate providers: Groq uses GROQ_API_KEY; xAI uses XAI_API_KEY or Grok OAuth. A /model grok shortcut in Hermes is the xAI alias, not Groq.
Can Hermes 3 call the same tools as Grok?
It can speak OpenAI-style tool calling on vLLM, or MCP via Hermes Agent. It does not get xAI built-in X Search unless you proxy that yourself.
Which is cheaper at 10 million tokens per month?
Usually Grok API tokens, because a 70B local cluster has idle GPU cost. Recalculate only after you have real GPU invoices.